🚀 Qwen представила QwenGyre: обучение ИИ-агентов стало до 1,85 раза быстрее Современные агенты могут выполнять задачи часами, генерируя сотни тысяч токенов. При обучении таких систем GPU часто простаивают, а повторяющиеся траектории расходуют вычислительные ресурсы. QwenGyre решает обе проблемы: • Elastic Scheduler динамически распределяет GPU между генерацией траекторий и обучением, не прерывая активные задачи. • Trajectory Processor объединяет разветвлённые траектории, удаляет дубликаты и учитывает даже частично выполненные задачи. Результаты впечатляют: → До 1,85× ускорения относительно Colocate. → До 1,78× относительно Async. → До 700 000 токенов на одну траекторию. → Рост точности на NL2RepoBench с 52,5% до 58,5% всего за 48 шагов обучения. 📄 Статья: https://arxiv.org/abs/2609.33848
From the original source:
Telegram — AI Machine Learning Big Data
Read full article at Telegram — AI Machine Learning Big DataThis material was compiled from public sources. If its publication affects your rights → Request removal
Qwen introduced QwenGyre: training AI agents has become up to 1.85 times faster
🚀 Qwen introduced QwenGyre: training AI agents up to 1.85 times faster Modern agents can perform tasks for hours, generating hundreds of thousands of tokens. When training such systems, GPUs are often idle, and repeated trajectories waste computing resources. QwenGyre…
AI Summary & Key Takeaways
- 🚀 Qwen introduced QwenGyre: training AI agents up to 1.85 times faster Modern agents can perform tasks for hours, generating hundreds of thousands of tokens
- When training such systems, GPUs are often idle, and repeated trajectories waste computing resources
Qwen introduced QwenGyre: training AI agents has become up to 1.85 times faster
Related stories
First households in Shalkiya village, Kyzylorda region connected to high-speed internet
In Shalkiya village, Kyzylorda region, the first subscribers were connected to high-speed internet with speeds up to 100 Mbps. Shalkiya became the first settlement connected under the 'Accelerated Digitalization for Inclusive Economy of Kazakhstan' project, implemented jointly…
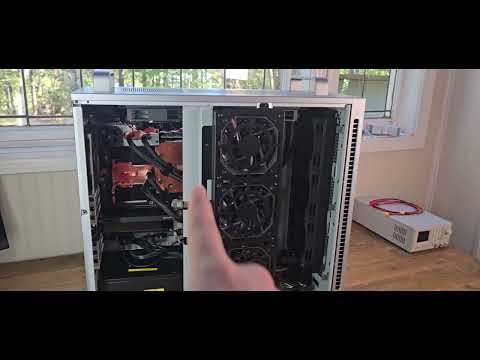
Datacenter at Home - GB300 GPU - w/ Asus DGX Station (ET900N G3)
What is going on everybody and welcome to a very exciting review of ASUS's take on the Nvidia DGX station. They're calling this the ET900N G3, but I'm going to keep calling it the DGX station or ASUS station for short. What we have here is 748 GB of coherent memory. That's kind…
Where the Blocks Live: Tier-Aware KV-Cache Routing for vLLM at Scale
Hi, I'm Pongup Pak from War at PyTorch Conference North America 2026. I'm presenting a poster called where the block lives. When GPU memory fmflows the KB cache to CPU or storage and LMD tracks where every block lives and sends each request to its cache. You will see when CPU is…
A Controlled LLM Workflow for Evidence-Grounded Diagnosis of Risk Score Differences
arXiv:2610.23962v1 Announce Type: new Abstract: We propose a controlled Large Language Model (LLM) workflow for explaining risk score differences using similar historical transactions. The workflow combines reference retrieval and contrastive SHapley Additive exPlanations (SHAP)…